-
An EU court adviser says Gemini may infringe publishers’ rights when it reproduces protected news content in chatbot answers.
-
The case was brought by Hungarian publisher Like Company against Google Ireland.
-
Reporting facts is not itself infringement, but reproducing an article’s protected expression can be.
-
The opinion is not legally binding, and the EU’s highest court has yet to deliver judgement.
November 4, (THEWILL) – Google‘s Gemini chatbot could breach European copyright law if it reproduces news articles so extensively that readers no longer need to visit the publishers that produced them, according to an opinion delivered to the European Union‘s highest court on Tuesday.
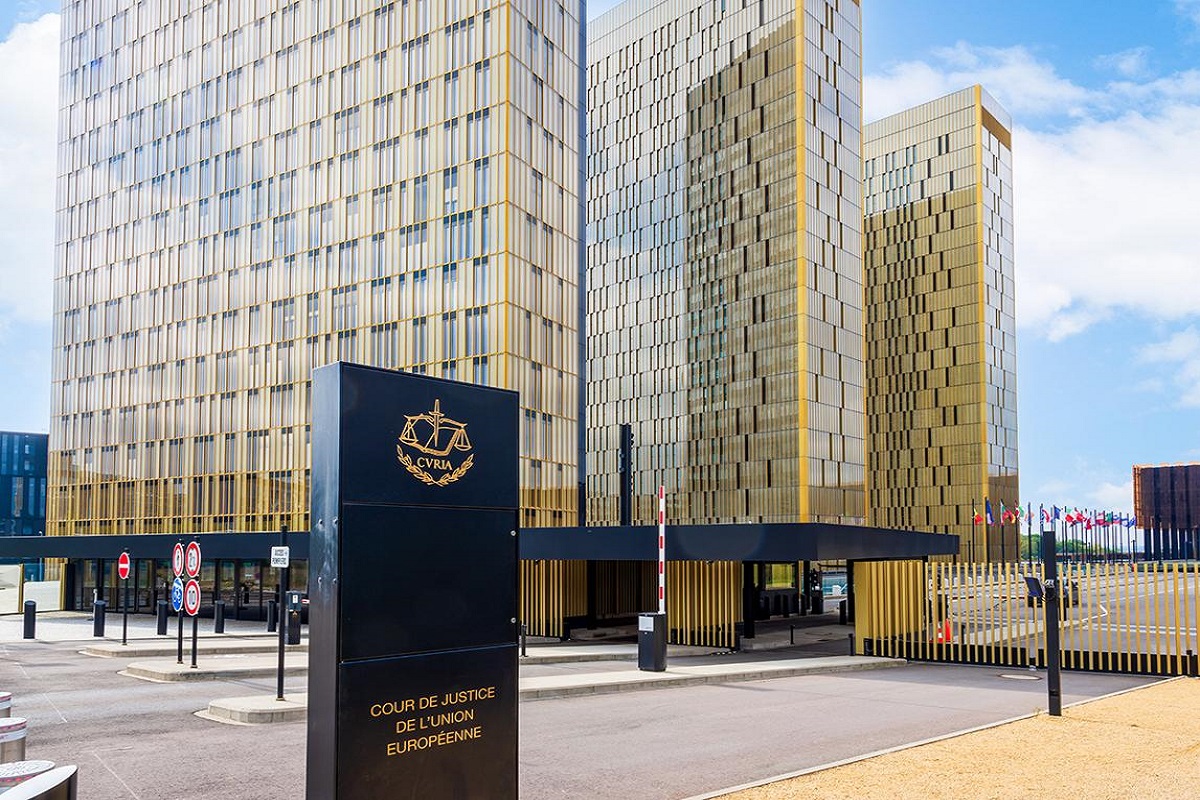
Advocate General, Maciej Szpunar, raised the concern in a case brought by Hungarian media company Like Company against Google Ireland, marking the first generative artificial intelligence dispute to reach the Court of Justice of the European Union.
His opinion, delivered on November 3, examines the legality of Gemini retrieving online news reports and incorporating their content into answers generated for users. It comes as publishers increasingly challenge technology companies over the use of their journalism in AI-powered services.
Unlike conventional search results that direct readers to websites, an AI chatbot can present information drawn from an article within its own response. For publishers whose revenue depends partly on readership, advertising and subscriptions, losing those visits could have financial consequences.
Where Reporting Facts Becomes Reproducing Journalism
Like Company operates Hungarian news websites and alleges that Gemini used its articles to train AI models and subsequently reproduced protected material in responses between June 2023 and May 2024.
Faced with the dispute, a Hungarian court sought guidance on how EU copyright provisions apply to large language models and the answers they generate.
Szpunar advised that infringement could arise when a chatbot circumvents effective technical protections, including paywalls, or reproduces an article’s original expression recognisably enough to replace the need to consult the publication.
His interpretation draws a boundary between information and the journalism used to communicate it.
Copyright generally does not protect the underlying facts of a news report. A chatbot can therefore relay factual information without necessarily violating a publisher’s rights. Problems arise when its output reproduces protected elements of the original reporting rather than independently conveying those facts.
For example, an AI answer explaining an interest-rate decision would not automatically infringe copyright simply because a newspaper reported the same decision. Reproducing substantial portions of that newspaper’s original account could raise a different legal question.
Szpunar also addressed the use of copyrighted material to train AI systems. He recommended that the court reject the training-related questions in this case because there was no evidence that Like Company’s articles had actually been used to train Gemini.
In his view, the EU’s text-and-data-mining exception generally permits such training, subject to the applicable legal requirements.
READ ALSO:
A Decision That Could Change AI’s Relationship With Newsrooms
Google maintains that Gemini generates original responses rather than copying source material and has pointed to controls available to rights holders.
Publishers, however, argue that AI-generated answers can compete directly with their reporting, particularly when readers obtain enough information from a chatbot to avoid visiting the original website.
The European Publishers Council has also warned against arrangements that effectively force news organisations to choose between protecting their content from AI reuse and maintaining visibility through search engines.
A future ruling could help determine how AI companies obtain, reproduce and distribute news content within the European market. It could also strengthen the commercial case for licensing agreements between AI developers and publishers, although the court has not ordered Google to pay compensation.
Its implications extend beyond Europe. Nigerian and other African publishers increasingly distribute journalism through the same global search platforms and AI services, making questions about attribution, traffic and payment relevant to their own digital businesses.
For now, Szpunar’s opinion remains advisory. Judges of the EU’s highest court will determine the interpretation of EU law, after which the Hungarian court must resolve the underlying dispute.
The outcome could clarify a question facing modern newsrooms as AI-generated answers become more common. Reporting a fact is one thing. Reproducing the work someone undertook to report it may be another.
Joy Onuorah is a business journalist and brand communications specialist covering financial markets, artificial intelligence, digital economy, and the ideas reshaping business across Africa and the global market. Beyond her reporting for TheWill, Joy uses brand strategy, storytelling, copywriting, and high-value SEO to help brands build lasting market authority.